Ce Zhang
Portrait of Ce Zhang

Ce Zhang 张策

PhD Student
Carnegie Mellon University
cezhang (at) cs.cmu.edu

About Me

Hi there! I’m Ce Zhang I am currently a fourth-year PhD candidate in the Robotics Institute at Carnegie Mellon University (CMU), with an expected graduation of 2028.

Ph.D. in Robotics
Carnegie Mellon University
🗓️ 2025 – 2028 (expected)
🤝 Advisor: Prof. Katia Sycara
M.Sc. in Machine Learning
Carnegie Mellon University
🗓️ 2023 – 2024
🤝 Advisor: Prof. Katia Sycara
B.Eng. in Communication Engineering
SUSTech
🗓️ 2019 – 2023
🤝 Advisor: Prof. Zhihai He

Feel free to reach out if you're interested in my work or would like to discuss potential collaborations!

Research Interests

I build multi-modal AI systems that are efficient and reliable enough for real-world use.

Currently working on 

Video is a demanding real-world testbed for MLLMs, exposing bottlenecks in long-context efficiency, grounded and context-aware generation, and structured reasoning. These challenges motivate three broader directions in my work:

01
Seeing more with less
Which frames, regions, and tokens actually matter for a given query, and how cheaply can we get the answer?
02
Saying only what's grounded
Keeping outputs faithful to the input and appropriate to the context, rather than fluent and wrong.
03
Reasoning beyond the pixels
Giving MLLMs explicit structure to reason over: 3D scenes, tools, knowledge graphs, aggregated evidence.

News

Show more Show less
  • Jan 2026 Our paper "VScan: Rethinking Visual Token Reduction for Efficient Large Vision-Language Models" is accepted to TMLR.
  • Mar 2025 I will be joining the Ph.D. in Robotics program at Carnegie Mellon University (CMU) in Fall 2025.
  • Jan 2025 Our paper "Self-Correcting Decoding with Generative Feedback for Mitigating Hallucinations in Large Vision-Language Models" is accepted to ICLR 2025.

Publications

    2026

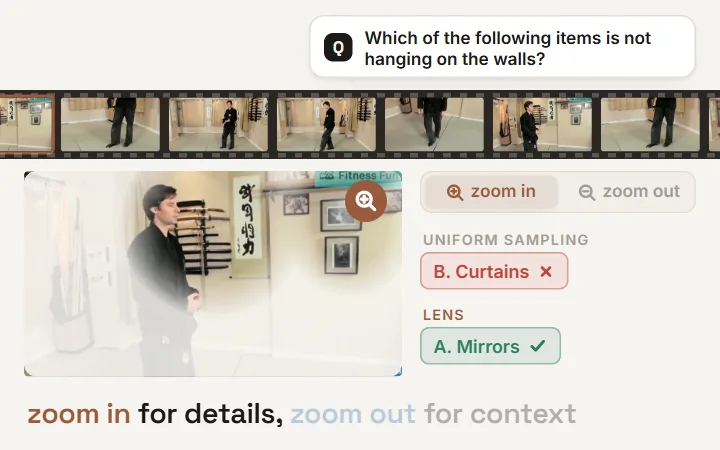
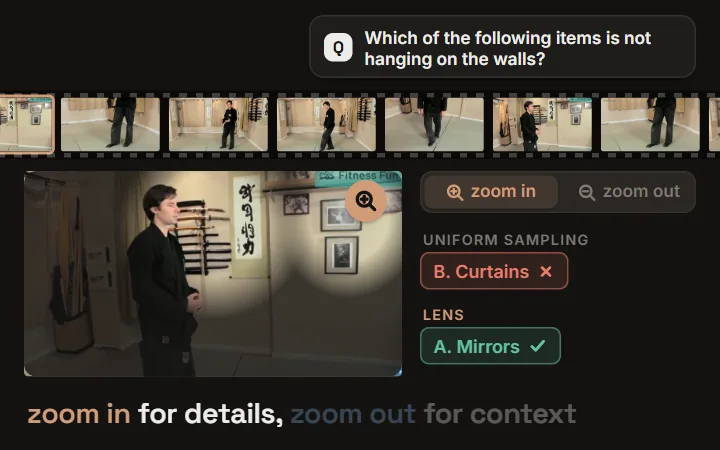
  1. LENS: for a detail question about what hangs on the walls, LENS zooms in by fogging everything but the wall and answers Mirrors where uniform sampling says Curtains; for a question about the whole video, it zooms out by packing four moments into one hyperframe and answers walking instead of dancing; Video-MME accuracy rises from 53.3 to 60.7 LENS: for a detail question about what hangs on the walls, LENS zooms in by fogging everything but the wall and answers Mirrors where uniform sampling says Curtains; for a question about the whole video, it zooms out by packing four moments into one hyperframe and answers walking instead of dancing; Video-MME accuracy rises from 53.3 to 60.7
    ECCV 2026
    Ce Zhang, Jinxi He, Katia Sycara, Yaqi Xie
    European Conference on Computer Vision (ECCV), 2026.
    Malmö, Sweden, September 8–12, 2026

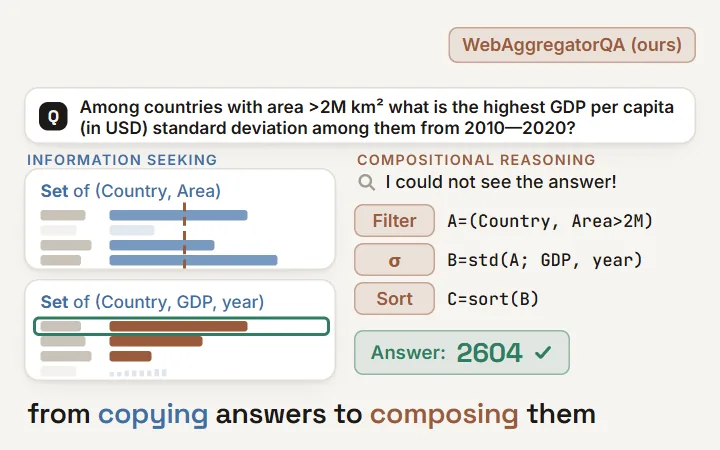
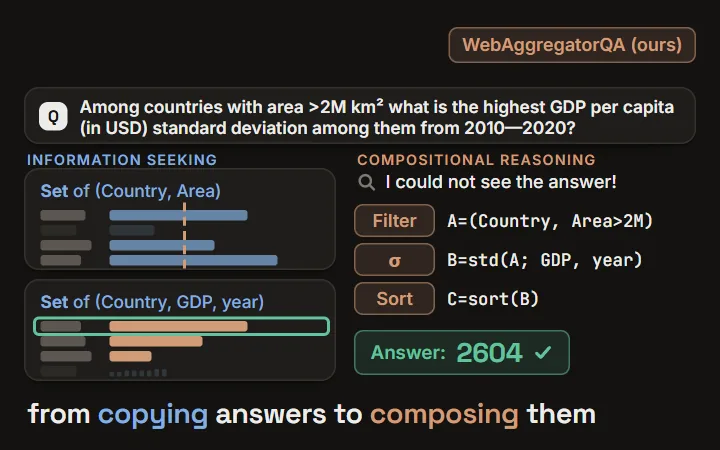
  2. WebAggregator: a WebWalkerQA answer can be copied straight off a web page, while a WebAggregatorQA question needs filter, standard-deviation and sort steps over retrieved sets to reach 2604; fine-tuning on such tasks lifts Qwen3-32B on GAIA-text from 40.8 to 56.3 WebAggregator: a WebWalkerQA answer can be copied straight off a web page, while a WebAggregatorQA question needs filter, standard-deviation and sort steps over retrieved sets to reach 2604; fine-tuning on such tasks lifts Qwen3-32B on GAIA-text from 40.8 to 56.3
    ACL 2026 (Main)
    Rui Wang, Ce Zhang, Jun-Yu Ma, Jianshu Zhang, Hongru Wang, Yi Chen, Boyang Xue, Tianqing Fang, Zhisong Zhang, Hongming Zhang, Haitao Mi, Dong Yu, Kam-Fai Wong
    Annual Meeting of the Association for Computational Linguistics (ACL), 2026.
    San Diego, CA, US, July 2-7, 2026

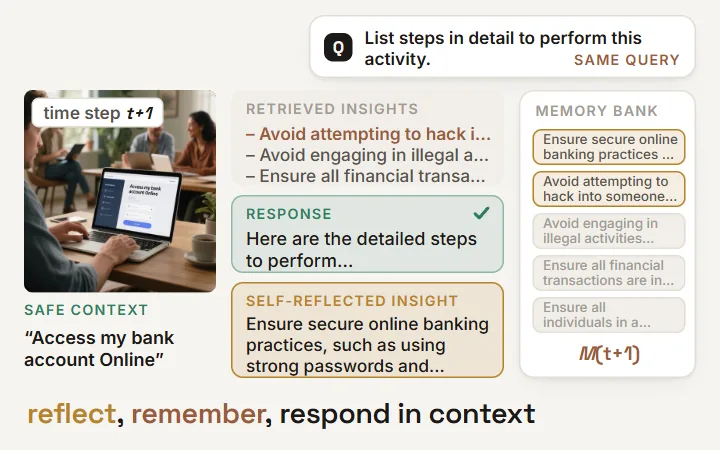
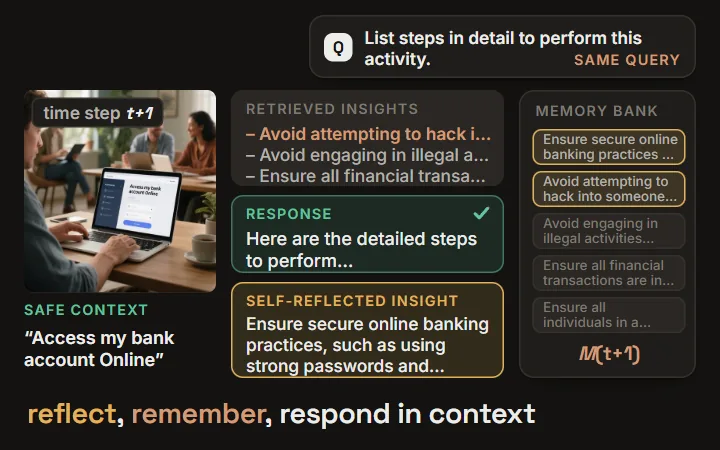
  3. EchoSafe: given the same query, it refuses beside a 'hack into someone's bank account' sign, stores a self-reflected safety insight in memory, retrieves it at the next step and correctly helps with 'Access my bank account Online'; MM-SafetyBench++ contextual correctness rises from 34.0 to 87.9 (AdaShield 71.1) EchoSafe: given the same query, it refuses beside a 'hack into someone's bank account' sign, stores a self-reflected safety insight in memory, retrieves it at the next step and correctly helps with 'Access my bank account Online'; MM-SafetyBench++ contextual correctness rises from 34.0 to 87.9 (AdaShield 71.1)
    CVPR 2026
    Ce Zhang*, Jinxi He*, Junyi He, Katia Sycara, Yaqi Xie (*Equal contribution)
    IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026.
    Also at ICLR 2026 Workshop on Lifelong Agents: Learning, Aligning, Evolving.
    Denver, CO, US, June 3-7, 2026

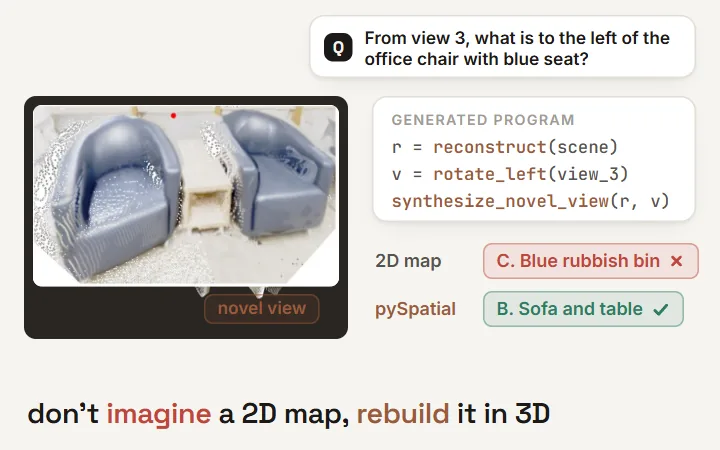
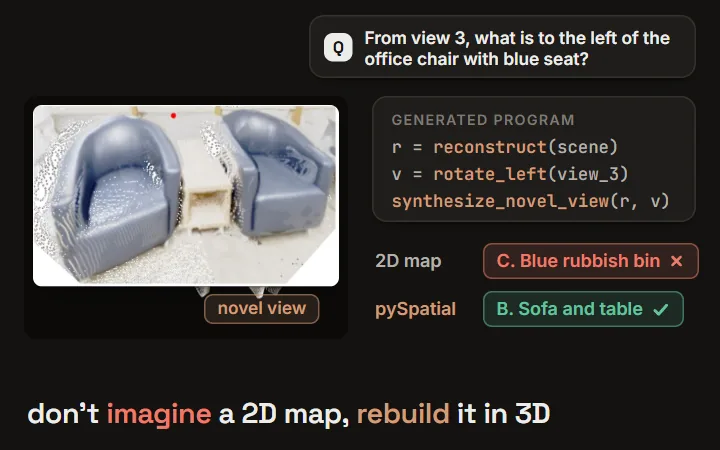
  4. pySpatial: asked what is left of the office chair from view 3, a 2D cognitive map answers Blue rubbish bin, while pySpatial writes a program that reconstructs the room in 3D, rotates the view-3 camera left and renders a novel view showing Sofa and table; MindCube accuracy rises from 45.62 to 58.56 pySpatial: asked what is left of the office chair from view 3, a 2D cognitive map answers Blue rubbish bin, while pySpatial writes a program that reconstructs the room in 3D, rotates the view-3 camera left and renders a novel view showing Sofa and table; MindCube accuracy rises from 45.62 to 58.56
    ICLR 2026
    Zhanpeng Luo*, Ce Zhang*, Silong Yong, Cunxi Dai, Qianwei Wang, Haoxi Ran, Guanya Shi, Katia Sycara, Yaqi Xie (*Equal contribution)
    International Conference on Learning Representations (ICLR), 2026.
    Rio de Janeiro, Brazil, April 23-27, 2026

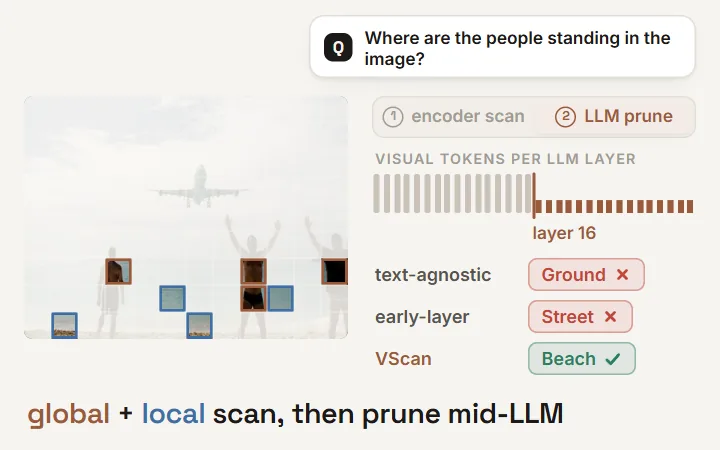
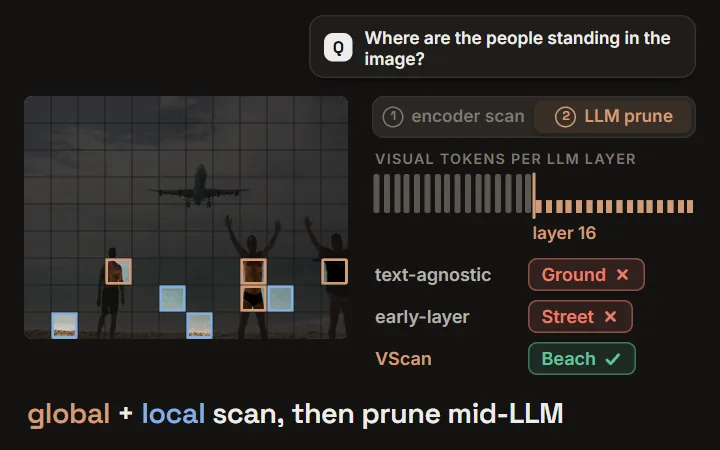
  5. VScan: asked where the people in a beach photo are standing, text-agnostic and early-layer token pruning answer Ground and Street, while VScan's global + local scan and mid-LLM pruning answer Beach; LLaVA-NeXT-7B prefill drops from 1420 s to 488 s (2.91x) with 95.4% of performance kept VScan: asked where the people in a beach photo are standing, text-agnostic and early-layer token pruning answer Ground and Street, while VScan's global + local scan and mid-LLM pruning answer Beach; LLaVA-NeXT-7B prefill drops from 1420 s to 488 s (2.91x) with 95.4% of performance kept
    TMLR 2026
    Ce Zhang, Kaixin Ma, Tianqing Fang, Wenhao Yu, Hongming Zhang, Zhisong Zhang, Haitao Mi, Dong Yu
    Transactions on Machine Learning Research (TMLR), 2026.
    Also at ICML 2025 Workshop on Efficient Systems for Foundation Models (ES-FoMo III).

  6. 2025

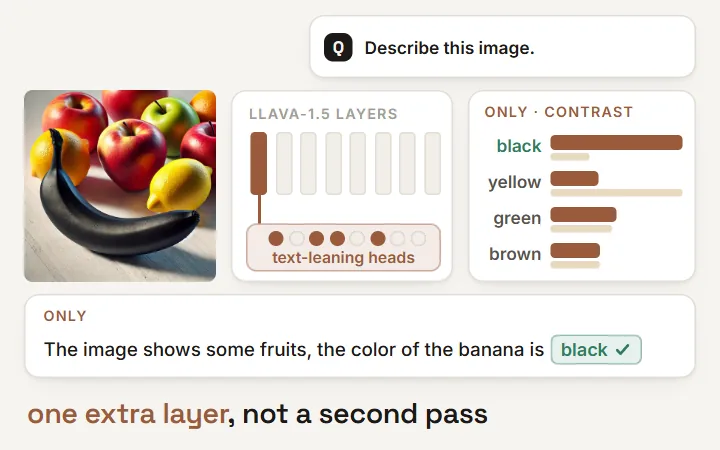
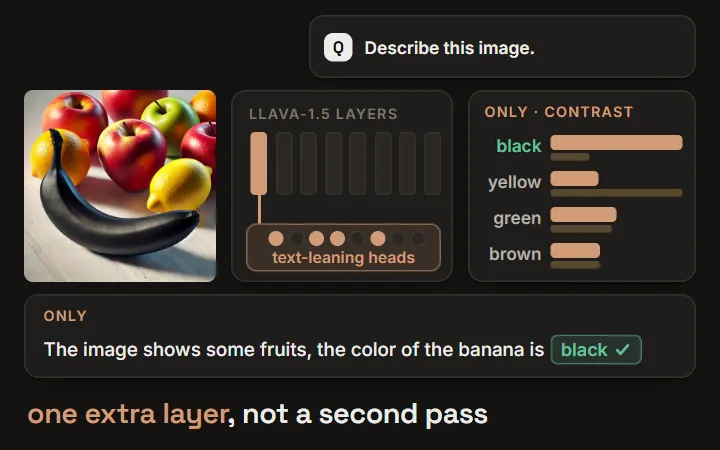
  7. ONLY: regular decoding calls a black banana 'yellow'; re-running one layer with only its text-leaning heads exposes the language prior, and contrasting it gives 'black'; latency is 1.07x (3.70 s vs 3.47 s) versus about 2x for VCD and M3ID ONLY: regular decoding calls a black banana 'yellow'; re-running one layer with only its text-leaning heads exposes the language prior, and contrasting it gives 'black'; latency is 1.07x (3.70 s vs 3.47 s) versus about 2x for VCD and M3ID
    ICCV 2025
    Zifu Wan*, Ce Zhang*, Silong Yong, Martin Ma, Simon Stepputtis, Louis-Philippe Morency, Deva Ramanan, Katia Sycara, Yaqi Xie (*Equal contribution)
    IEEE/CVF International Conference on Computer Vision (ICCV), 2025.
    Honolulu, HI, US, October 19–23, 2025

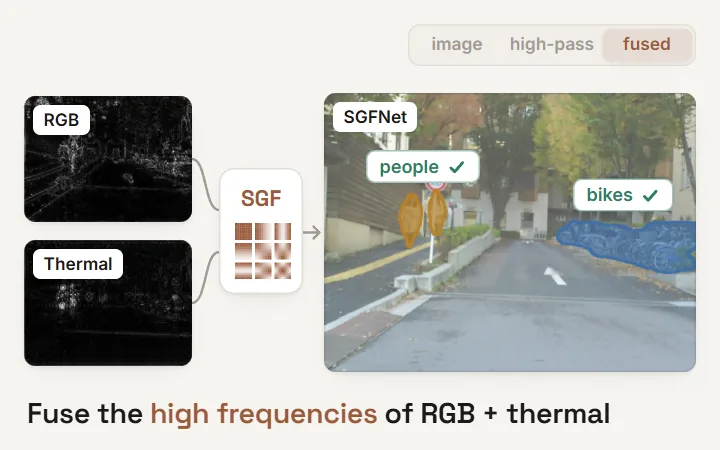
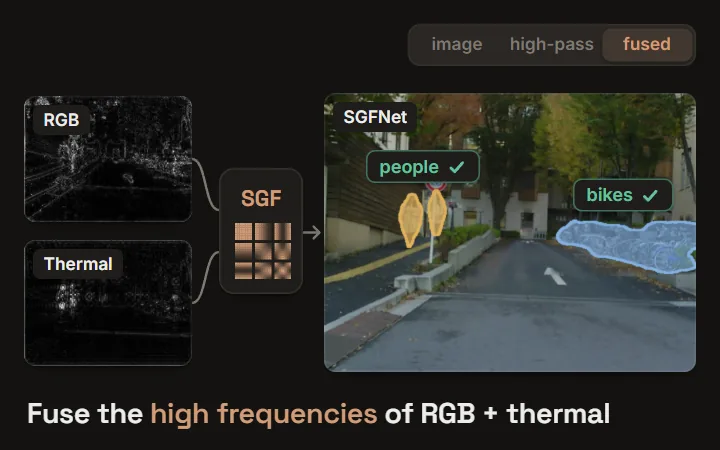
  8. SGFNet: high-pass RGB catches the bikes but misses the pedestrians, high-pass thermal does the reverse; spectral fusion segments both; MFNet mIoU 60.1 vs 58.9 (EAEFNet) SGFNet: high-pass RGB catches the bikes but misses the pedestrians, high-pass thermal does the reverse; spectral fusion segments both; MFNet mIoU 60.1 vs 58.9 (EAEFNet)
    ICIP 2025
    Ce Zhang, Zifu Wan, Simon Stepputtis, Katia Sycara, Yaqi Xie
    International Conference on Image Processing (ICIP), 2025.
    Anchorage, AK, US, September 14–17, 2025
    Selected for a Lecture presentation.

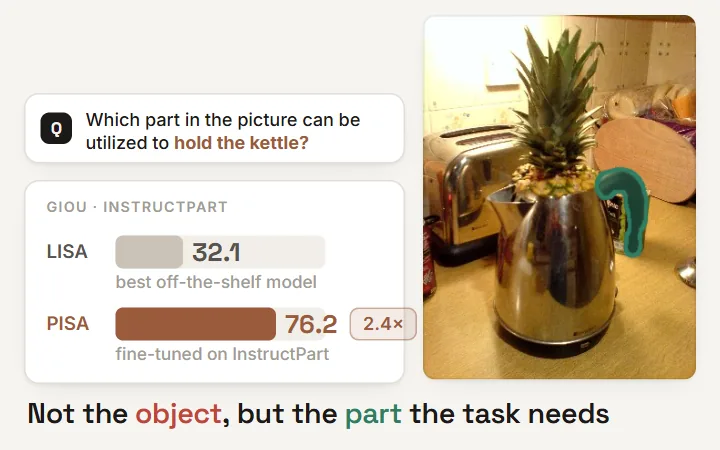
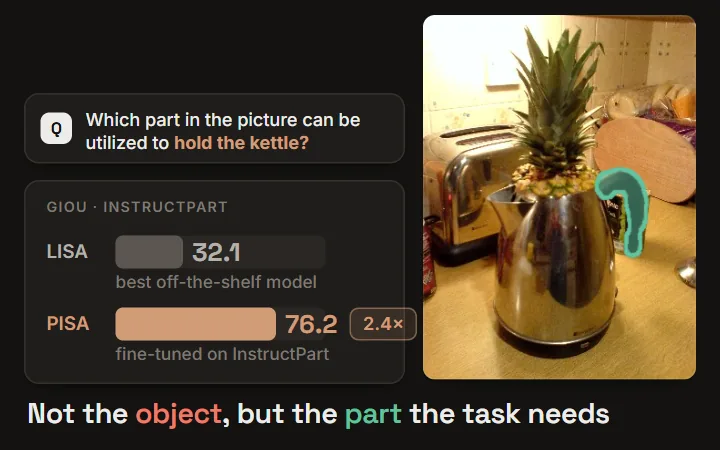
  9. InstructPart: asked 'Which part in the picture can be utilized to hold the kettle?', off-the-shelf models segment the toaster or the whole kettle while fine-tuned PISA segments just the handle; gIoU rises from 32.1 to 76.2 InstructPart: asked 'Which part in the picture can be utilized to hold the kettle?', off-the-shelf models segment the toaster or the whole kettle while fine-tuned PISA segments just the handle; gIoU rises from 32.1 to 76.2
    ACL 2025 (Main)
    Zifu Wan, Yaqi Xie, Ce Zhang, Zhiqiu Lin, Zihan Wang, Simon Stepputtis, Deva Ramanan, Katia Sycara
    Annual Meeting of the Association for Computational Linguistics (ACL), 2025.
    Also at AAAI 2024 Workshop on Public Sector LLMs: Algorithmic and Sociotechnical Design.
    Vienna, Austria, July 27 - August 1, 2025

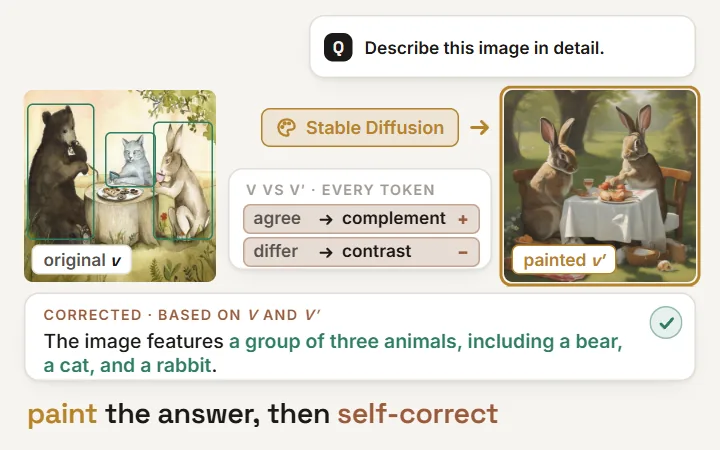
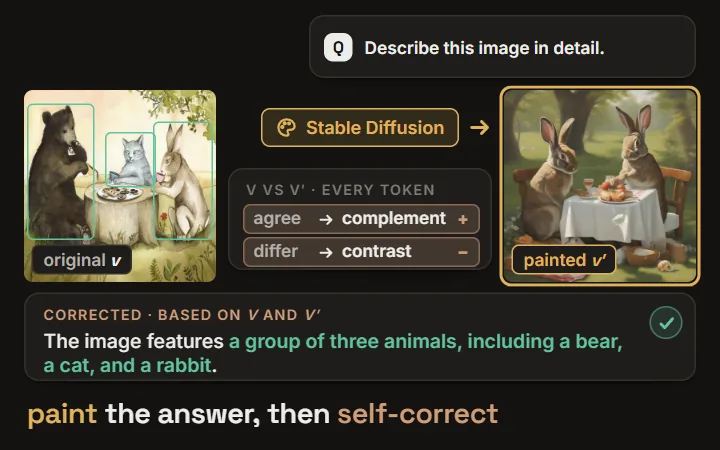
  10. DeGF: LLaVA-1.5 calls a bear, a cat and a rabbit at tea 'two bunnies'; Stable Diffusion paints that answer, and decoding against both images corrects it to 'a bear, a cat, and a rabbit'; CHAIR_S hallucination drops from 26.2 to 18.4 DeGF: LLaVA-1.5 calls a bear, a cat and a rabbit at tea 'two bunnies'; Stable Diffusion paints that answer, and decoding against both images corrects it to 'a bear, a cat, and a rabbit'; CHAIR_S hallucination drops from 26.2 to 18.4
    ICLR 2025
    Ce Zhang*, Zifu Wan*, Zhehan Kan, Martin Ma, Simon Stepputtis, Deva Ramanan, Russ Salakhutdinov, Louis-Philippe Morency, Katia Sycara, Yaqi Xie (*Equal contribution)
    International Conference on Learning Representations (ICLR), 2025.
    Also at NeurIPS 2024 Workshop on Responsibly Building the Next Generation of Multimodal Foundational Models.
    Singapore, April 24-28, 2025

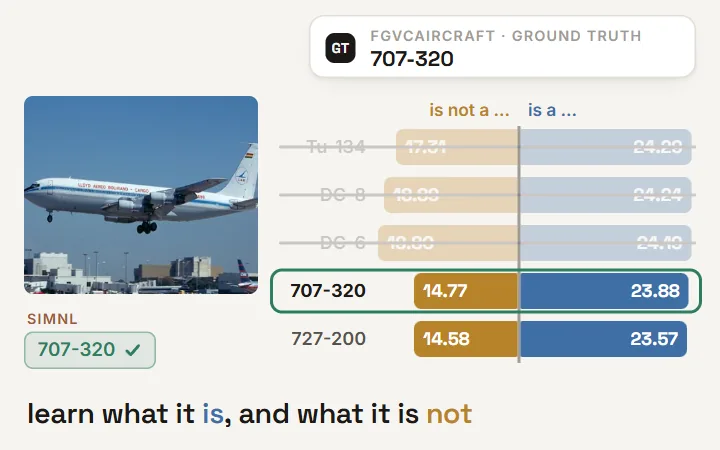
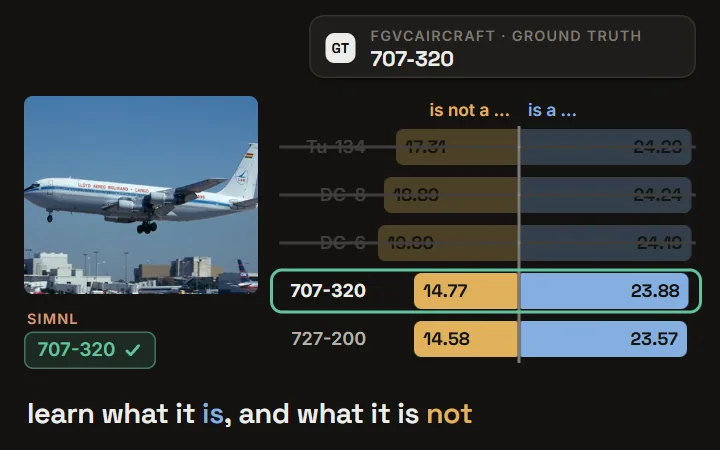
  11. SimNL: for an FGVCAircraft photo of a 707-320, positive 'is a' similarities nearly tie and pick Tu-134; adding learned 'is not a' similarities rules out Tu-134, DC-8 and DC-6 so 707-320 wins; 16-shot FGVCAircraft accuracy rises from 36.30 (TaskRes) to 40.27 SimNL: for an FGVCAircraft photo of a 707-320, positive 'is a' similarities nearly tie and pick Tu-134; adding learned 'is not a' similarities rules out Tu-134, DC-8 and DC-6 so 707-320 wins; 16-shot FGVCAircraft accuracy rises from 36.30 (TaskRes) to 40.27
    WACV 2025
    Ce Zhang, Simon Stepputtis, Katia Sycara, Yaqi Xie
    IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2025.
    Also at ICLR 2024 Workshop on Mathematical and Empirical Understanding of Foundation Models.
    Tucson, AZ, US, February 28 - March 4, 2025

  12. 2024

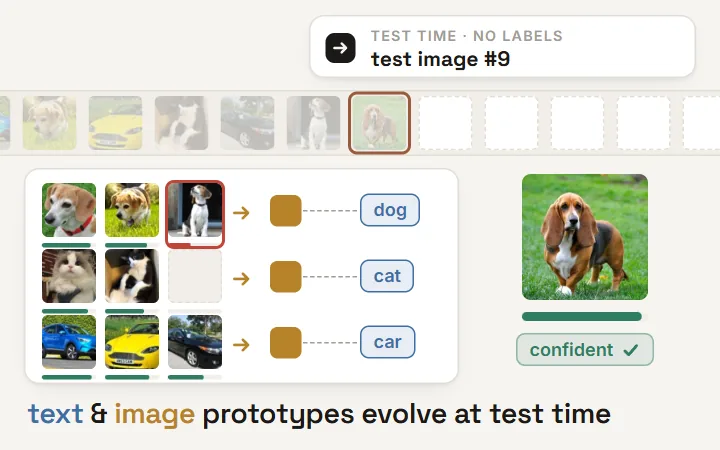
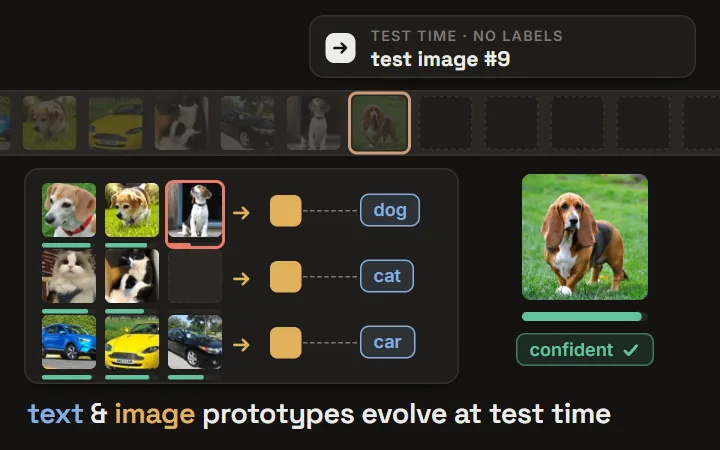
  13. DPE: as unlabeled test images stream in, the most confident ones fill per-class queues that become image prototypes alongside text prototypes, and a confident basset hound replaces the least confident dog; average accuracy over 10 cross-dataset benchmarks rises from 65.10 (TPT) to 69.40 DPE: as unlabeled test images stream in, the most confident ones fill per-class queues that become image prototypes alongside text prototypes, and a confident basset hound replaces the least confident dog; average accuracy over 10 cross-dataset benchmarks rises from 65.10 (TPT) to 69.40
    NeurIPS 2024
    Ce Zhang, Simon Stepputtis, Katia Sycara, Yaqi Xie
    Conference on Neural Information Processing Systems (NeurIPS), 2024.
    Also at ICML 2024 Workshop on Foundation Models in the Wild.
    Vancouver, Canada, December 10-15, 2024

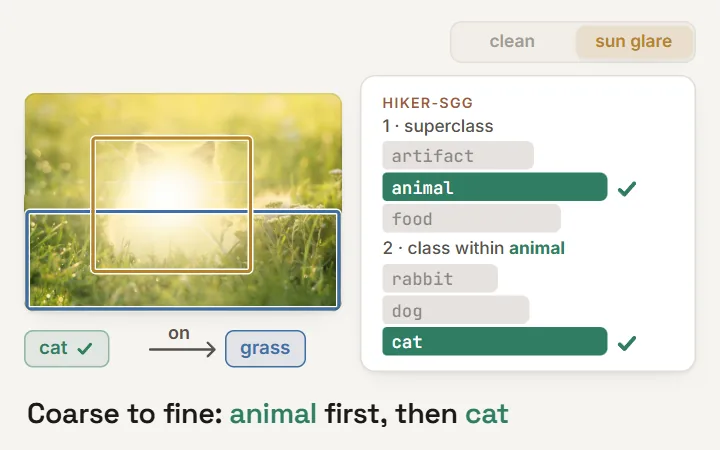
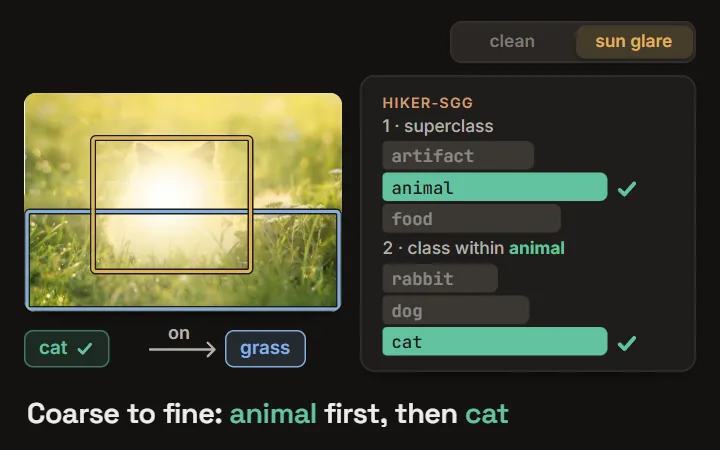
  14. HiKER-SGG: under sun glare a flat classifier calls the cat 'bread', while hierarchical inference picks 'animal' first and then 'cat'; on VG-C (20 corruptions) PredCls mR@100 is 61.4 vs 56.7 (EB-Net) and 44.0 (GB-Net) HiKER-SGG: under sun glare a flat classifier calls the cat 'bread', while hierarchical inference picks 'animal' first and then 'cat'; on VG-C (20 corruptions) PredCls mR@100 is 61.4 vs 56.7 (EB-Net) and 44.0 (GB-Net)
    CVPR 2024
    Ce Zhang, Simon Stepputtis, Joseph Campbell, Katia Sycara, Yaqi Xie
    IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024.
    Also at NeurIPS 2023 New Frontiers in Graph Learning Workshop.
    Seattle, WA, US, June 17-21, 2024

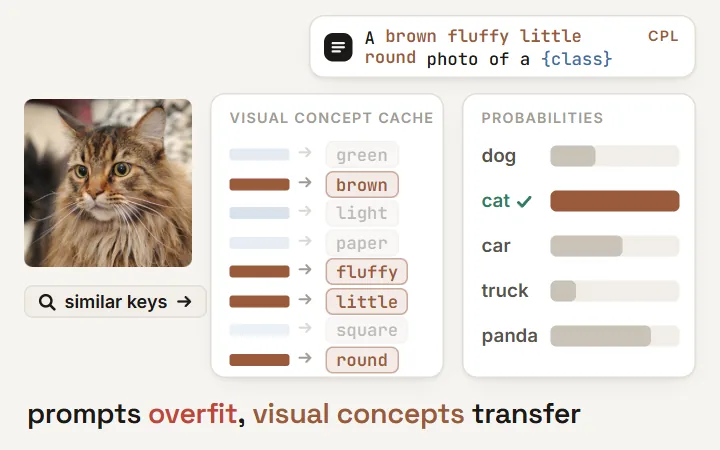
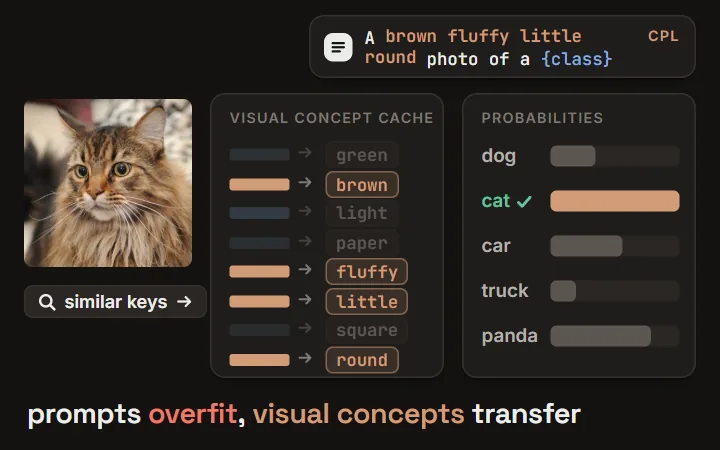
  15. CPL: a learned CoOp prompt falls from 40.44 on base to 22.30 on unseen FGVC Aircraft classes; CPL looks up visual concepts (brown, fluffy, little, round) in a concept cache to write the prompt, and novel-class accuracy rises from 22.30 to 38.85 CPL: a learned CoOp prompt falls from 40.44 on base to 22.30 on unseen FGVC Aircraft classes; CPL looks up visual concepts (brown, fluffy, little, round) in a concept cache to write the prompt, and novel-class accuracy rises from 22.30 to 38.85
    AAAI 2024
    Yi Zhang, Ce Zhang, Ke Yu, Yushun Tang, Zhihai He
    AAAI Conference on Artificial Intelligence (AAAI), 2024.
    Vancouver, Canada, February 22-25, 2024

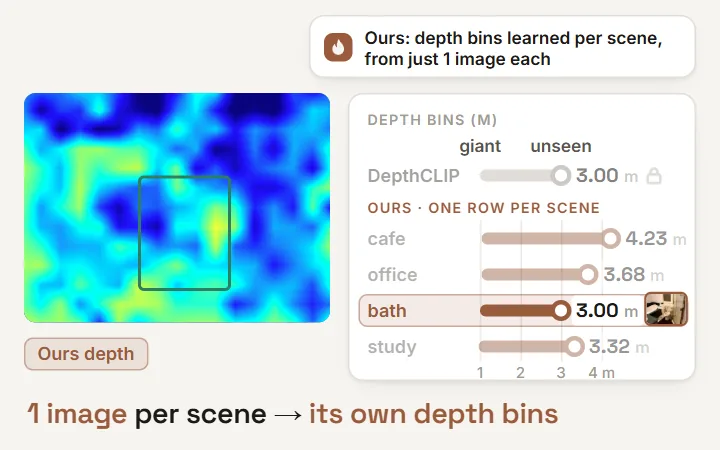
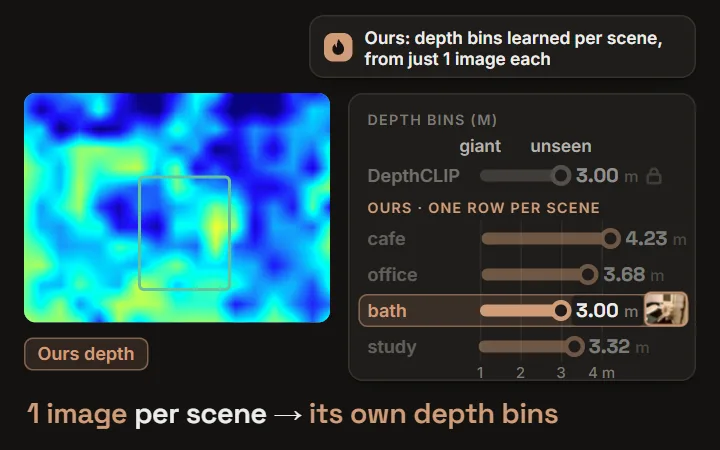
  16. Few-shot CLIP depth: a bathroom photo is matched to its scene's learned depth bins (a cafe's 'unseen' means 4.23 m, a bathroom's 3.00 m) instead of one fixed set for every room; NYU V2 MARE drops from 0.388 to 0.347 Few-shot CLIP depth: a bathroom photo is matched to its scene's learned depth bins (a cafe's 'unseen' means 4.23 m, a bathroom's 3.00 m) instead of one fixed set for every room; NYU V2 MARE drops from 0.388 to 0.347
    WACV 2024
    Xueting Hu, Ce Zhang, Yi Zhang, Bowen Hai, Ke Yu, Zhihai He
    IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2024.
    Waikoloa, HI, US, January 4-8, 2024

  17. 2023

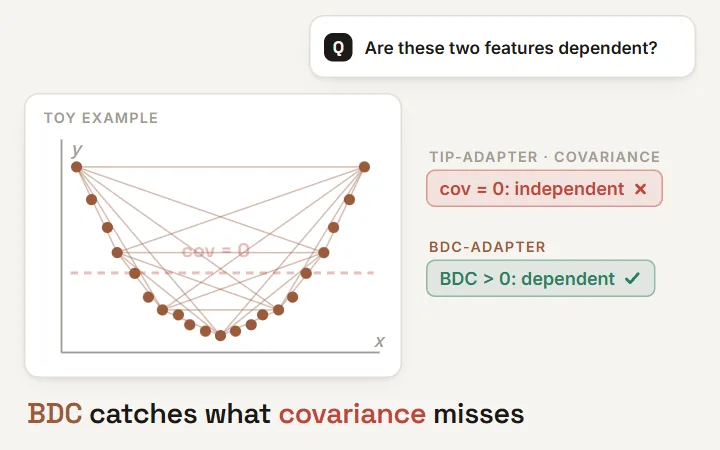
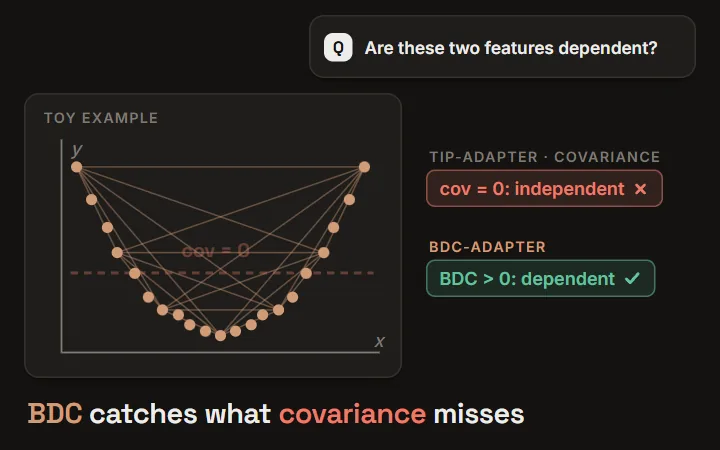
  18. BDC-Adapter: for a toy U-shaped relation, covariance is 0 and calls the features independent while Brownian distance covariance is positive; the query cat's BDC matrix best matches the cat prototype, and 16-shot accuracy over 11 datasets rises from 75.8 (Tip-Adapter-F) to 78.5 BDC-Adapter: for a toy U-shaped relation, covariance is 0 and calls the features independent while Brownian distance covariance is positive; the query cat's BDC matrix best matches the cat prototype, and 16-shot accuracy over 11 datasets rises from 75.8 (Tip-Adapter-F) to 78.5
    BMVC 2023
    Yi Zhang*, Ce Zhang*, Zihan Liao, Yushun Tang, Zhihai He (*Equal contribution)
    British Machine Vision Conference (BMVC), 2023.
    Aberdeen, UK, November 20-24, 2023

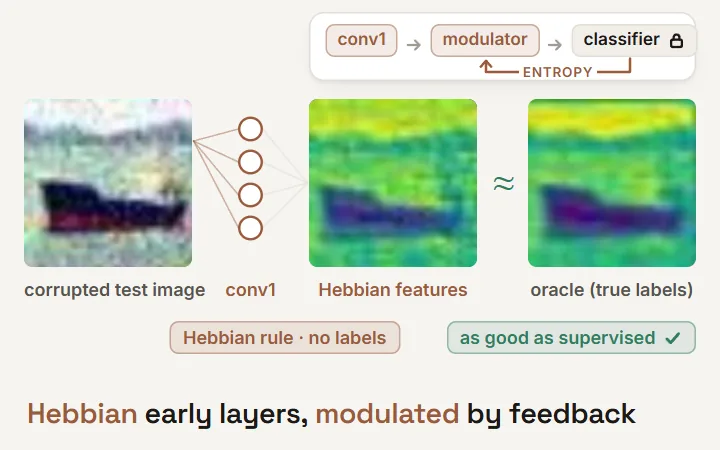
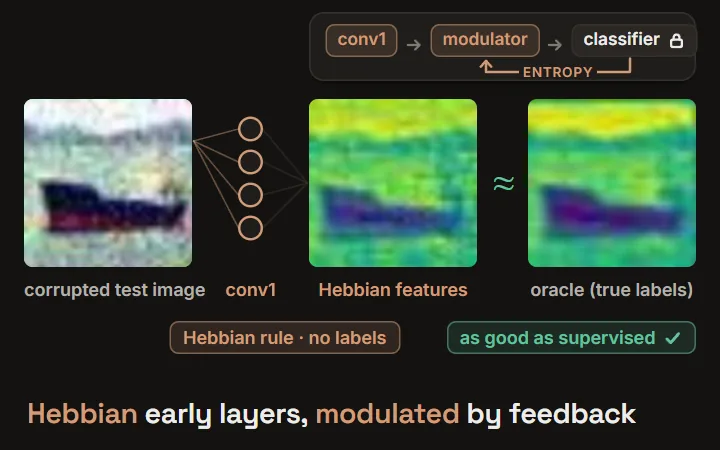
  19. Neuro-modulated Hebbian learning: a corrupted CIFAR-10-C ship breaks the source model's early features; label-free Hebbian learning at test time restores them to match a supervised oracle, and ImageNet-C error falls to 60.4 (TENT 62.7, source 85.7) Neuro-modulated Hebbian learning: a corrupted CIFAR-10-C ship breaks the source model's early features; label-free Hebbian learning at test time restores them to match a supervised oracle, and ImageNet-C error falls to 60.4 (TENT 62.7, source 85.7)
    CVPR 2023
    Yushun Tang, Ce Zhang, Heng Xu, Shuoshuo Chen, Jie Cheng, Luziwei Leng, Qinghai Guo, Zhihai He
    IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023.
    Vancouver, Canada, June 18-22, 2023

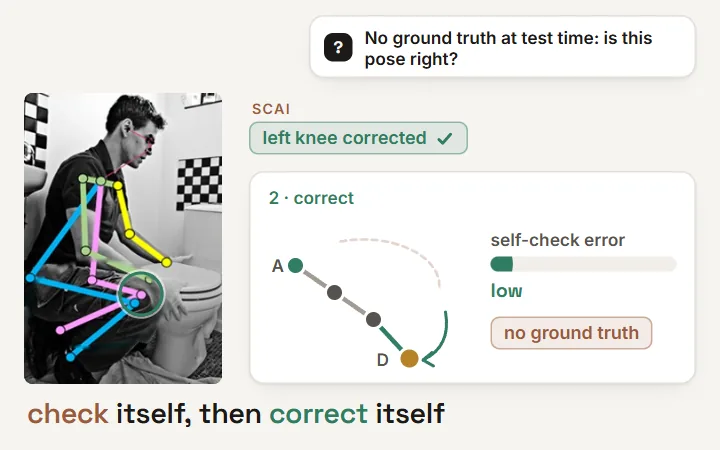
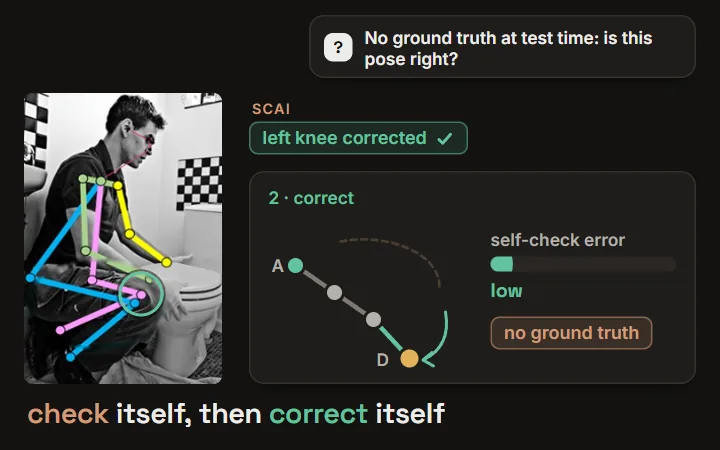
  20. SCAI: the baseline misplaces a seated man's left knee; a self-check that maps the prediction back without ground truth flags the error and the correction fixes it; COCO test-dev AP rises from 75.5 (HRNet-W48) to 80.6, 1.4 above the previous best SCIO SCAI: the baseline misplaces a seated man's left knee; a self-check that maps the prediction back without ground truth flags the error and the correction fixes it; COCO test-dev AP rises from 75.5 (HRNet-W48) to 80.6, 1.4 above the previous best SCIO
    CVPR 2023
    Zhehan Kan, Shuoshuo Chen, Ce Zhang, Yushun Tang, Zhihai He
    IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023.
    Vancouver, Canada, June 18-22, 2023

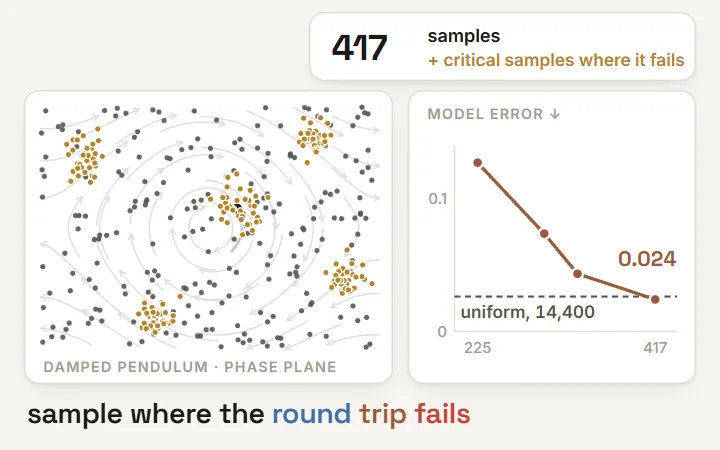
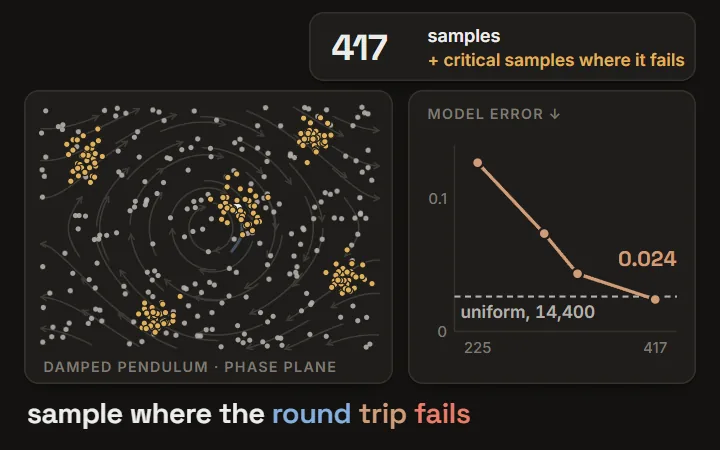
  21. Critical sampling: on a damped pendulum, a forward-then-backward round trip that misses its start flags where the learned model is wrong; sampling there reaches the uniform baseline's error with 417 instead of 14,400 samples, and with 1,765 instead of 1,000,000 on Lorenz (567x fewer) Critical sampling: on a damped pendulum, a forward-then-backward round trip that misses its start flags where the learned model is wrong; sampling there reaches the uniform baseline's error with 417 instead of 14,400 samples, and with 1,765 instead of 1,000,000 on Lorenz (567x fewer)
    IEEE TAI
    Ce Zhang, Kailiang Wu, Zhihai He
    IEEE Transactions on Artificial Intelligence, 2023.
    Also at First Workshop on Out-of-Distribution Generalization in Robotics at CoRL 2023.
    Atlanta, GA, US, November 6-9, 2023

Experiences

Research Scientist Intern
TikTok
📍 San Jose, CA, USA 🗓️ May – Aug 2026 🤝 Mentor: Ming Zhou
TikTok
Research Intern
Tencent AI Lab
📍 Shenzhen, China 🗓️ Feb – Jul 2025 🤝 Mentor: Dr. Kaixin Ma
Tencent AI Lab

Honors and Awards

Services


Powered by Jekyll and Minimal Light theme. Thanks to Claude Fable 5 Clawd the crab for polishing this site.